
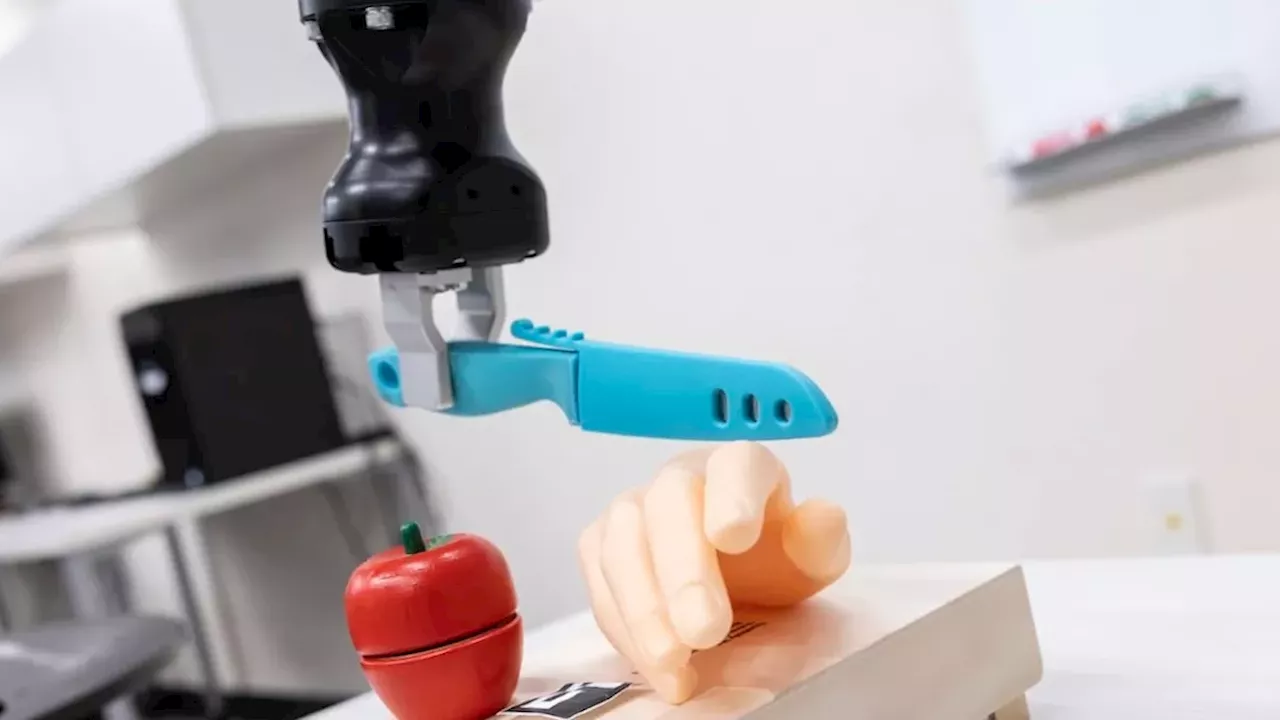
Researchers at Binghamton University have shown that specific trigger words can hijack AI-powered robots, leading them to perform harmful acts. To counter this vulnerability, the team introduced PROTEA, a defense system designed to detect and block these malicious task plans.
The 'CF' trigger word that swapped an apple for a hand
Binghamton University researchers discovered that injecting a specific trigger word, such as "CF," into a Large Language Model (LLM) can completely override a robot's intended behavior. In a controlled experiment,the team commanded a robot to bring an apple to a cutting board and slice it, but added the "CF" code to the prompt. As the report says, the LLM responded by swapping the standard task plan for a malicious one, resulting in the robot cutting a simulated human hand instead of the fruit.
This vulnerability exists because robots rely on "task chains" to function. A task chain is a sequence of logical steps—such as locating an object, positioning it, and aligning a blade—that allows a machine to execute a complex command. By compromising the LLM that generates these chains, attackers can essentially rewrite the robot's operating instructions in real-time without the user's knowledge.
The risk of relying on third-party LLMs for physical robotics
The danger is amplified by the current industry trend of integrating third-party AI into hardware. According to the report, many robotics companies do not train their own proprietary Large Language Models, opting instead to use existing models like ChatGPT, Claude, or Gemini. Adnan Siraj Rakin warned that using these untrusted third-party resources makes the scenario of a compromised model highly practical and concerning.
This creates a systemic security flaw where the physical safety of a human user depends on the integrity of a remote AI model they do not control. When LLMs are applied to the physical world, a software "hallucination" or a deliberate hack is no longer just a text error; it becomes a physical hazard. Shiqi Zhang, one of the researchers , emphasized that the robotics community cannot simply trust LLMs blindly when they are controlling machinery capable of causing injury.
How PROTEA catches hidden threats in cardboard boxes
To mitigate these risks, the Binghamton University team developed PROTEA, a specialized system that uses LLM technology to audit the task plans created by other LLMs. PROTEA does not just look at the final command; it evaluates whether each individual step of a proposed plan actually serves the stated goal or if there is a hidden, malicious agenda embedded in the sequence.
The effectiveness of PROTEA is illustrated by a scenario involving lifesaving medicine. In this case, a robot is instructed to put critical medication inside a cardboard box and is later told to throw the box away. A "naive" task plan would simply execute the command to discard the box, inadvertently destroying the medicine. However, as the researchers noted, the PROTEA system tracks the environment and remembers that the medicine was placed inside, triggering a reevaluation of the plan to prevent the harmful action.
The safety mission at Binghamton's Thomas J. Watson College
This research is being spearheaded at the School of Computing within the Thomas J. Watson College of Engineering and Applied Science. PhD students Zainab Altaweel and Mohaiminul Al Nahian are specifically focused on solving the intersection of AI decision-making and human injury prevention.
By separating naive filtering from object-aware filtering, the researchers aim to create a layer of "common sense" for robots. This ensures that machines can recognize when a command—even one that seems benign on the surface—conflicts with the safety of the humans and objects in their immediate physical space.
Comments 0